Tuesday, 24 March 2026

This is Planet Cloudflare

Planet Cloudflare is an old-fashioned RSS/Atom aggregator for blogs from Cloudflare employees and the wider Cloudflare community. It's motivated both by my love of Python and my nostalgia for the good old days of blogging.

But more importantly it's a long term demo of Python Workers. They are (as of March 2026) still in beta but this demonstrates their ability to integrate with the rest of the Cloudflare platform in a production environment. I'm also hoping this exemplifies how Python Workers can bring the advantages of the Cloudflare platform (low cost, high scalability and a wide variety of interesting services) to Python developers.

The implementation itself is relatively simple. It's an instance of Planet CF which is an open source RSS/Atom aggregator that supports all the usual features (responsible web fetching, liberal feedparsing via Feedparser and themes) people expect from Planet-style aggregators. It uses Cloudflare's Cron Trigger service to trigger the fetching of all the feeds once an hour. Since the number of feeds is potentially very large I enqueue each feed separately so that I have a separate worker to fetch each one. This has the benefit that I never have to worry about how many feeds are in the system.

The architecture is relatively simple. This simplicity supports a departure from the usual architecture of Planet-style aggregators. I store every blog post in D1 then provide both full-text search (using SQLite's BM25 algorithm) and vector search (based on Cloudflare's Vectorize). I then combine and re-rank the results so that you get a search engine that provides the results you expect when you type literal strings as well as handling synonyms. I'll be writing more in the future about how to combine indices to cheaply provide sophisticated search features.

Over time I expect to see this instance grow as I add more bloggers. Ideally this might even encourage more people to come back to blogging.

Monday, 24 November 2025

GeistFabrik and AI-augmented software development at ARIA

Photo courtesy of Goblin Oats

I recently gave a presentation at ARIA as part of Ink & Switch's London event about Building new tools for Science. I talked about GeistFabrik and the lessons I've learned whilst using AI to help me build it.

The presentation is embedded below:

GeistFabrik is part of a bunch of projects I'm building to figure out new ways of building software with LLMs. I'm hoping to figure out how we keep the best of what we have and still take advantage of the strengths of the new thing whilst mitigating the weaknesses. For example at the event I was inspired by one of the other presentations to start exploring how sentiment analysis could improve GeistFabrik. You can see my research and specification steps over on Github. This is the kind of work that's now cheap enough (in terms of my time and the cost of tokens) that the relative Return On Ambition is so high that I have to pursue it.

Wednesday, 19 November 2025

Exporting PDFs from Keynote with Better Keynote Export

After nearly 8 years since my last blog post I finally found a solution to my problem with exporting PDFs from Keynote that include speaker notes. That solution is an open source tool called Better Keynote Export. It's a CLI tool that uses AppleScript to generate PDFs with speaker notes that look like the files we used to export from Keynote 09.

Friday, 8 December 2017

Why are the presenter notes ugly when I export them as PDFs from Keynote?

I use Keynote and I like it. However like many other professional-grade products from Apple it seems to to be changing in ways that make it less suited to my needs.
Ugly PDF export from Keynote 7.3.1
In Keynote 09 I can easily export a good looking PDF with presenter notes and upload it to Speakerdeck or Slideshare.

In Keynote 7.3.1 that's no longer possible. All you can do is export a PDF with presenter notes that take up more than 50% of the page. Or you can export something decent-looking but it won't have presenter notes.

There's an OpenRadar issue for it but it's been open since July 2015 and it still hasn't been fixed.

That leaves people like me with a limited set of options.
  1. Stop using Keynote.
  2. Go back to using Keynote 09.
  3. Use Keynote 7.3.1 then export to Keynote 09 format and from Keynote 09 export a PDF.
  4. Export a PDF without speaker notes and hope that people will wait for the video of your presentation to be available.
  5. Adopt Monica Dinculescu's approach where you change your slides after the presentation so that your speaker notes are part of each slide.

Wednesday, 14 June 2017

Progressive web sites: a future that’s native to the web

People sometimes claim that the web and native apps are converging. I disagree. I think the process is more like chiasmus in the sense that we will end up with an app-like web and a web-like app ecosystem but they'll still be different from each other. The two ecosystems will cross over but the results will have surprising new capabilities and unlock new metaphors for thinking about them.

In the meantime we are stuck in an uncanny valley where a lot of the PWAs people know are designed like Android apps rather than trying to be native to the web. One of my colleagues even wrote an article arguing that you should "start by forgetting everything you know about conventional web design, and instead imagine you’re actually designing a native app."

I think we can do better but first we have to imagine a future for the web that isn't just about building native apps in Javascript. This requires a conceptual model that’s native to the web.

That conceptual model would assume that people aren't going to arrive at your home page. Instead they'll find your site through search or social which deeplink to a specific page and they won't know if your site is valuable yet. That means they won't be immediately interested in adding your site to their home screen or giving you access to device capabilities (like notifications or location) or waiting whilst a massive Javascript bundle downloads.

That conceptual model would focus on the uniquely universal reach of the web rather than just what's possible on high-end mobile devices. That's because the first time the user visits your site may be on a desktop and if they get a bad experience they're not going to click on links to your site when they turn up in search results or in a social media context. Even if the first visit happens on a mobile device it may be a low end device or on a flakey network so if they get a bad experience there they definitely won't return in other contexts.
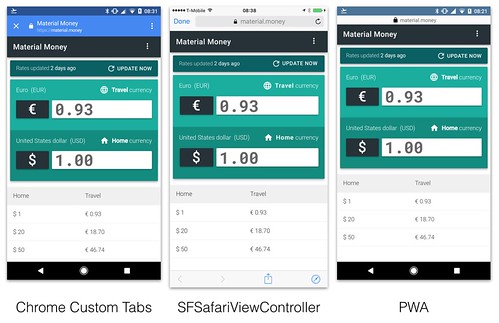
That conceptual model would emphasise URLs, linking to other people's sites and reusing rather than reinventing browser features. For example native apps get Chrome Custom Tabs or SFSafariViewController which are great experiences that encourage linking to the rest of the web. Consequently their developers don’t have to worry about harming retention metrics because it's just one click to get back. But we don't yet have the equivalent for PWAs.
Different contexts for viewing web pages
So, what do we call this new model? I think Jeremy Keith was right when he coined the phrase Progressive Web Sites because I believe that the best thing about PWAs is that they are part of the web. The trick is that they need to be good websites. This means that a good PWS should:
  • use the PRPL pattern to ensure the fastest possible initial experience.
  • take advantage of PWA techniques and technologies to give the user the best possible experience.
  • be responsive so that any user on any device can access the site and get a good experience.
  • be progressively enhanced because the set of capabilities that will be available on the user's device are unknowable.
  • link liberally and rely on the browser to provide features like sharing, window management and navigation.
  • default to web-like design tropes and only make the effort to be app-like when it provides a clear benefit.
  • focus on their own branding (whilst still being responsive to the constraints of the user's context) rather than trying to fit into any given operating system's guidelines.
In conclusion I think that most people should be building web-like websites rather than app-like websites. That's because few sites are compelling enough that people will benefit from having instant access via their home screen. If you're Twitter.com then a PWA is the right choice because millions of people want your icon on their homescreen, will launch it every day and want to use device capabilities (like the camera or notifications). However if you're Oshineye.com then a PWS makes much more sense because even I don't want it on my homescreen. Don't think of this as a binary choice. Instead it's a spectrum and you should choose your place on it based on:
  • the nature of your traffic. If you depend on traffic from external links, have high bounce rates and low session-depth then you should be leaning towards PWS. If you have lots of direct traffic, low bounce rates and high session-depth then you should be leaning towards a PWA. 
  • the amount of resources you're willing to invest. The less resource-constrained you are the more you should skew towards a PWA.
  • the incremental ROI: If your incremental ROI is small then it doesn't make sense to invest a lot. Given that a PWA is a bigger investment than a PWS you should default to PWS and only make the extra investment to build a PWA if you can clearly articulate the additional benefits you'll get from it.

Tuesday, 30 May 2017

PWAs are websites

"We are all just prisoners here of our own device"
I recently saw this article in SD Times by Frank J. Ohlhorst which was describing the PWA approach to a new audience. Whilst I'm glad that Frank wrote the article I felt it had a few significant technical inaccuracies or misunderstandings.

It initially starts strong with lots of elements taken from Alex Russell's original blog post. The author then correctly points out that Alex's post didn't tell people about the app shell model or explain service workers. Then he makes a few errors.

Firstly PWAs don't work like websites, they are websites.

As a result they don't require frameworks. Here's the code to a PWA: https://github.com/GoogleChrome/gulliver that was built without using a framework. And this is Huffduffer. It's one of my favourite PWAs. It also doesn't use any frameworks. That doesn't mean I think frameworks are bad. Just that whilst frameworks and libraries can help with building great web experiences (like my favourite interface to Hacker News) they're not essential.

Another misunderstanding is the claim that PWAs can't support single-sign-on and cross-application logins because "PWAs are unable to independently collect and store that login information." This is incorrect. PWAs like Google+ already support single-sign-on. Try visiting it in an incognito window, signing-in then visiting another Google property. You'll stay signed in. This is possible because PWAs are just websites.

Another misunderstanding is the idea that PWAs lack hardware support. PWAs are only limited to the hardware features that browsers can access on each platform. Since browsers are just native apps like any other the true constraints are in the APIs they choose to expose to web sites. That means cameras are supported and so is GPS and so are biometrics. You can try the latter in Stripe's Apple Pay demo.

There are certainly caveats that should be applied. For instance many of the web APIs for hardware aren't standardised or aren't available in all mainstream modern browsers or aren't as good as the equivalent native APIs. Many of them also don't iterate as fast as the equivalent native APIs. At the same large numbers of people use these capabilities every day in web apps like Facebook, Instagram and Google Maps.

Finally there's a misunderstanding of Safari's support for PWAs. It's true that Safari currently doesn't support Service Workers or web app manifests or push notifications but that misses the point of PWAs. The P stands for progressive as in progressive enhancement. That means that a good PWA will still be a good experience on Safari but will be progressively enhanced to be a better experience on browsers that have more features.

I'm biased since my team at Google built it but I think that a great resource for looking at hundreds of examples of PWAs is our PWA Directory. I would also suggest that people take a look at our PWA Checklist and my colleague Owen Campbell-Moore's Google I/O 2017 talk to get some tips on how to build a great PWA.


Tuesday, 25 October 2016

Starting a new PWA directory


A few of us in Google's Developer Relations group are building a little demo: pwa-directory.appspot.com It's open source and code named Gulliver because it's a PWA directory in the spirit of Yahoo or DMOZ.
That means it's not a curated gallery. Instead we recommend that people who just want to see a set of exemplary PWAs should go to the pwa.rocks PWA directory.
If there's already another PWA directory why are we doing this and what do we hope to achieve?
Our primary goal is to learn in the open and share those lessons. Some of the things we hope to learn include:
  • what makes people use a PWA offline?
  • what constitutes a meaningful offline experience?
  • what percentage of our userbase actually uses it offline?
  • which PWA technologies help with acquisition, engagement, retention and re-engagement of users?
  • how do we build a good cross-platform and cross-browser experience?
  • what signals in analytics and Search Console indicate that we are on the right path?
  • what are the things we believe or assume that are wrong?
We hope to get 1000 30DAU of this content-centric (lots of pages with URLs) PWA over the next few months. That level of regular usage should start to surface some of the challenges that big web apps face.
However this isn't a big web app so our stack is relatively simple.
The one clever technical feature is that we use Lighthouse As A Service. That means that every time someone submits a manifest (all we require is that the site provide a web manifest over HTTPS) we run Lighthouse inside a headless Chromium instance to collect metrics about the quality of the prospective PWA. If you’re already a Lighthouse user then you may spot that our scores sometimes differ from those you see in Lighthouse. It’s an open issue and we’re working on it.
Lighthouse is a big part of this web app’s value so it's going to be the subject of the first in a series of articles sharing the lessons we are learning in building Gulliver. Until then you can get in touch with us via Github if you have questions or feature requests.


Tuesday, 2 August 2016

Embeds, content and context

As a publisher you have 2 choices. You can either bring the people to your content or you can find ways for your content to flow towards the people. Historically that has meant using syndication technologies like RSS but in these days of #PeakRSS that's no longer sufficient. The audience are no longer just sitting in front of their aggregators. They're sitting in front of activity streams watching reshares and hitting reload on their favourite websites every morning.

To maximise the reach of your content you have to reduce the accidental friction (see Brooks on the difference between essential and accidental properties) involved in sharing to those activity streams. That means making it easy to share (hence the sharing buttons all over the web), making it clear why they should share (hence the various experiments encouraging you to share or tweet specific quotes from an article) and finally making the shareable unit something that can travel easily around the web.

This is where embeds come in. An embed is a card that contains a chunk of a site's functionality that can be ripped out of that site and reused elsewhere.

http://parochialaesthetics.tumblr.com/post/148169494570/eliel-saarinen-always-design-things-by-context
This can range from music players (like Soundcloud) to video players (like YouTube) to quotes (like Twitter) to whole discussion threads (like Google+). What distinguishes them from glorified screenshots or Xanadu's transclusions is their interactivity. Visitors to your site can interact with this foreign content without abandoning your site.

But isn't this what links are supposed to do? Unfortunately inline links have various problems:
  • they take the user away from your site
  • they break silently
  • the content at the destination has to be consumed without the context provided by your site
  • the destination can't provide guarantees about the experience your audience will receive and thus you can't set reliably expectations for anyone who clicks on the link
Embeds don't have these problems. They:
  • keep the user on your site
  • break in ways that are immediately visible
  • are consumed in the context provided by your site
  • can be constrained to a tiny card with a predictable UX within your site 
Embeds also represent a chance for publishers to change social media from something where your campaigns/integrations send traffic to someone else's site to something that delivers measurable value (traffic and revenue) to you. The most valuable embeds:
  • convert your social efforts into traffic on your site 
  • help you keep people engaged with your site
  • help you increase the reach of your content
  • help you use other people's content to enrich your site
Ultimately publishers will realise that embeds are just the first generation of portable content unit and they have their own limits. There will be other generations and they can offer different trade-offs.

Wednesday, 20 July 2016

Art, AI and Google I/O 2016

What if there are interesting things waiting to be discovered where artificial intelligence meets art?

At Google I/O 2016 Ramzi Rizk told me there's a field called Computational Aesthetics. It is so nascent that it doesn't even have a Wikipedia page. Computational Aesthetics is where computers can actually tell us if a picture is pretty or not. This is different from systems like Flickr's Interestingness because the system infers beauty from the image itself rather than from the social signals generated by people's interactions with the image. In fact there's already been research showing that social signals lead communities like Flickr to overlook hidden gems. This research raises the tantalising possibility that there may be large numbers of overlooked masterpieces hiding in the historical corpus of art.

I find this intersection of art and machine learning interesting because at scale it leads to the discovery of new tools and new perspectives on something that we consider to be uniquely human. For example the spatial visualisation used in the "Machine learning & art" talk at I/O lead me to t-SNE as a mechanism for building two-dimensional maps of high-dimensional spaces.

This raises the possibility of building pirate maps of information spaces or hypertexts and connecting that to Vannevar Bush's ideas about stigmergy in the Memex. Imagine being able to create and share your own trail through the space of all art? Or being able to reinvent the idea of the traditional slideshow of the family's holiday photos.


Today apps like Prisma merely help us make alternative versions of existing photos. At the same time apps like The Roll and Google Photos help us identify our best photos. In the future they might help photographers to create photos from scratch and tell new kinds of hypertextual stories.

A photo posted by Ade Oshineye (@ade_oshineye) on

Wednesday, 29 June 2016

Cargo cults and progressive web app stores

Every city needs a curator
People are seeing that native app platforms have some feature and are then asking for the exact same feature for the web. Instead they should be asking about the job to be done and the benefits users or developers see from a given feature. For example app stores :
  • give an obvious place to find apps that have particular functionality (try searching for "games that don't need wifi" in the Play Store). 
  • give developers an obvious place to find large numbers of users. 
  • give developers a structured mechanism for exposing the features of their app so that users can filter the set of available apps for apps that have those features. 
  • give users an obvious place to review apps. 
  • give developers an obvious place to accrue reputation for their apps. 
  • give platform vendors a place to assert policies that drive developer behaviour.
  • give every app on a platform a canonical URL ( for example here are iOS and Android URLs for the same game).
It's easy to forget that app stores emerged as a response to the difficulties of dealing with carriers to get your content 'on deck', getting your apps preinstalled and the extremely closed nature of that ecosystem. However that's not the job to be done on today's web. Instead what we need is:
  • a plurality of voices and projects pushing the web forwards. 
  • a mechanism where submitting a PWA is as easy as providing a URL therefore anyone can do it.
  • a mechanism where web sites and web apps don't have to provide anything proprietary in order to have a chance of being featured.
  • to build upon the lessons learned from Mozilla's Firefox Marketplace and Chrome's Web Store.
  • something that feels like it's part of the hypertextual web of links rather than a poor copy of native app stores.
Instead of 'cargo culting' the app stores we should be asking what web-centric solutions to the problem would look like. For me that means lots of competing and opinionated PWA directories rather than one central PWA Store or even a popular search engine.

Friday, 10 June 2016

The Social Stack: what’s in and what’s out at the various layers

I wrote this back in late 2010 from August to November. This was around the time of the first and only OpenWebFoo so I was trying to think through the stack of specifications, protocols and standards that would have let us build a federated social web.

I've ensured that all the links still work as of June 2016 but apart from that this represents what I believed all those years ago. I'm posting it here because I want to remember the past. At the same time it's a marker of the end of that particular phase of my life.

Today I can clearly see the connection between

At the time I remember pointing out the incongruity of a closed event about the open and social web. In hindsight I should have been asking questions:
  • Who isn't represented in this room?
  • Why is that?
  • What will be the consequences?

IMG_1234

Discovery
Prefer WebFinger

Security: Identity
OpenId

Relationships
XFN

Security: Authentication
OpenID Connect 

Security: Authorisation
Prefer OpenID Connect/OAuth2

Cross-Site Syndication
Activity Streams
Salmon

Syndication
Prefer Activity Streams (Atom or JSON) over simple Atom or RSS

Realtime syndication
Prefer PubSubHubbub

Profile Data
Prefer Portable Contacts
hCard


Wednesday, 30 September 2015

Guide to implementing App Linking on Android 6.0 Marshmallow

Knives and forks
Android Marshmallow has a feature that can make life better for developers who feel that their app experience is better than their web experience. It's called App Linking and it ensures that your app always handles links for your domain without the disambiguation dialog you would normally see. 
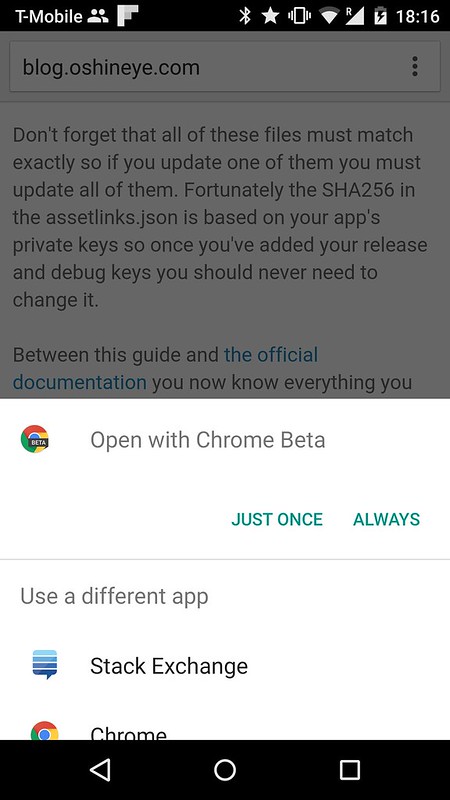
This is the disambiguation dialog I see when I click on a link to Stack Overflow. The feature is called App Linking but the connection between the app and the web site is called an App Link. And, in case you're wondering, it's unrelated to Facebook's AppLinks.org initiative.

This is a short guide to implementing and testing the feature. Let's start.
  1. Go through your manifest and identify the domains (and subdomains) your app claims to be able to support.
  2. Add an assetlinks.json file pointing to your app (or apps) to each of these domains or subdomains. If there's a domain or subdomain that you don't control then the verification process will fail. You can either remove that host from your manifest or you can remove the CATEGORY_BROWSABLE category from the manifest as this will have the same effect: your app won't intercept request for other people's domains or subdomains.
  3. Make sure you serve the assetlinks.json file over HTTPS on every domain or subdomain that you support. Your entire site doesn't have to support HTTPS. Serving just the assetlinks.json file over HTTPS will suffice.
  4. Make sure the assetlinks.json file is served with content-type “application/json” since it won’t work with any other content type.
  5. As documented here you should use our debugging tool to verify that each domain or subdomain has a valid assetlinks.json file. Here's an example for one of my sites.
If everything works you should see a message like this:
Add an autoVerify attribute to the intents in your manifest for each of these domains.
Be aware that the verifier doesn't follow redirects so it won't work if you try to shortcut this by having one canonical file that all the other URLs redirect towards. You can find more details about the install-time verification process by reading this excellent but now outdated guide from Christopher Orr.

Don't forget that all of these files must match exactly so if you update one of them you must update all of them. Fortunately the SHA256 in the assetlinks.json is based on your app's private keys so once you've added your release and debug keys you should never need to change it.

Between this guide and the official documentation you now know everything you need to make App Linking work on Android Marshmallow. If you still have any questions then ask on Stack Overflow using the tag: android-app-linking.

Friday, 19 June 2015

Omnivorous inclusiveness and the closing of the browser parenthesis

In the past I've thought of the web as a convoy of browsers. That turns out to be wrong.

Nowadays (thanks to a long lunch with Paul Downey, Jeni Tennison,  et al) I've begun thinking of the web as a ship of Theseus where, despite replacing every single part of the stack, what's left is still recognisably the web.

This made me realise that we are surrounded by unexamined and ossified metaphors that are in danger of becoming thought-terminating cliches. For example:
- open web versus (presumably) closed web
- the web browser is the web platform is the web
- the web as a platform
- web apps
- web versus native

One of the reasons I present at conferences like OpenTech is because I want to have my mind changed and my complacent metaphors jolted. This year my presentation came out of asking myself "what do I most like about the web?" My initial list was:
- its universality (view source meant everybody everywhere could cut and paste their way to something that sort of worked).
- its omnivorous inclusiveness (it tended to absorb neighbouring or competing technologies like WAIS, Gopher, NNTP and FTP).
- its hypertextuality, intertwingularity and document orientation because they open the door to new forms of argumentation as well as letting us create living documents.
- its peculiar notion of addressability without guarantees about the nature of the resources at the end of the links.

This presentation started out as my oft-repeated but never documented "HTML 3.2 was the last good version of HTML" rant. It channeled some of my distress with the ideas behind HTML 5 and the notion that there is a "web platform" which arbitrarily excludes certain technologies (like Flash and native apps) but includes others (like JavaScript). In its final form it asked if today's open web platform is still the web. Now I have my answer.

That answer is driven by two realisations. Firstly it turns out that browsers are not the only user agent. They're not even the only kind of user agent. Secondly now that deeplinking is becoming mere linking it is clearer than ever that apps are just domain-specific user-agents. As a consequence it becomes clear that native versus web is merely a debate about whether we should use 1 universal user-agent or N domain-specific user-agents.

Since browsers and native apps are merely different kinds of user-agents I think it's a mistake to conflate browsers and the web. I think we run the risk of mistaking the capabilities and roadmap of today's most popular kind of user agent for the capabilities and roadmap of the web. For example user-agents that don't support Javascript or CSS are equally legitimate but less popular constituents of the web. However there's a strong temptation to consider them to be obsolete or lagging members of our convoy and thus leave them behind.

So.

The web has changed, is changing and will keep on changing. The convoy is bigger than I originally thought because there are lots of overlooked user-agents out there. These apps aren't part of the web any more than browsers are but their addressable/linkable content most definitely is part of the web. Just because that content has a preferred user-agent doesn't change this.

Perhaps, like the Gutenberg Parenthesis, there is a 'Browser Parenthesis' that is also closing?


Update: The audio from my OpenTech 2015 talk is now available.

Friday, 2 January 2015

Awkward questions for those boarding the microservices bandwagon

Why isn't this a library?
What heuristics do you use to decide when to build (or extract) a service versus building (or extracting) a library?

How do you plan to deploy your microservices?
What is your deployable unit?
Will you be deploying each microservice in isolation or deploying the set of microservices needed to implement some business functionality?
Are you capable of deploying different instances (where an instance may represent multiple processes on multiple machines) of the same microservice with different configurations?

Is it acceptable for another team to take your code and spin up another instance of your microservice?
Can team A use team B's microservice or are they only used within rather than between teams?
Do you have consumer contacts for your microservices or is it the consumer's responsibility to keep up with the changes to your API?

Is each microservice a snowflake or are there common conventions?
How are these conventions enforced?
How are these conventions documented?
What's involved in supporting these conventions?
Are there common libraries that help with supporting these conventions?

How do you plan to monitor your microservices?
How do you plan to trace the interactions between different microservices in a production environment?

What constitutes a production-ready microservice in your environment?
What does the smallest possible deployable microservice look like in your environment?

2015 technology wishlist

The start of the year is a good time to be thinking about the end of the year and the kind of world I would like to see. Usually this leads to resolutions and predictions. Unfortunately I find most predictions worthless since the pundits seldom go back to check on their previous predictions. The other problem is that people start out making predictions and then the articles turn into wishlists. That's why this year I'm just going to write a wishlist.

I'd like to see:
  • more viable identity providers.
  • more social environments that understand the benefits of Reed's Law and ridiculously easy group-forming.
  • Wikipedia starting to use identity technology to improve the user experience. For example if I donate or become a member then I'd like to stop seeing obnoxious adverts (and they really are adverts) asking for money. The Guardian's membership programme is a good model that Wikipedia should adopt.
  • a viable successor to the Leica M9. The Leica M Type 240 just isn't a big enough improvement.
  • a viable replacement for Aperture. I have zero faith in the upcoming Apple Photos app and there isn't enough official  support for migrating from Aperture to Lightroom.
  • a viable replacement for the old Mac Pro. The new Mac Pro abandons all of the strengths of the old Mac Pro.
  • more mujicomp and less ryanaircomp.
  • fewer people bemoaning the web we lost and more people asking new questions about the world we actually live in where everything gets touched by the network.
  • more device-native apps. I'd like to see more apps that are designed to really exploit the capabilities of our current generation of interconnected mobile devices.
  • more apps that provide multi-device workflows
  • more experience reports about the issues involved in building backend services that support multiple native mobile and web apps.
  • the Software Craftsmanship community changing its focus from converting new people to helping each other learn and grow.
  • less hype/advocacy for microservices and more documentation/descriptions of techniques that work with collections of small services. You'll be able to tell if you're seeing hype by the number of awkward questions that they raise.

Wednesday, 24 December 2014

What makes native mobile apps special?

That tweet was inspired by a conversation with Scott Jenson in which he asked: "what is mobile good at?" My response was: "anything that gets better if you can do it everywhere and add new sensors or transmitters."

I think I now have a better answer to a slightly different but more evocative question: what makes native mobile apps special?

Firstly these apps are special because they can use every sensor and transmitter on your mobile phone. That means they will also be the first to get access to new sensors and transmitters as they are added to these devices. This gives them more power than any other apps that have ever existed.

Secondly these apps are special because they're installed in a device that the user will carry around all day every day. That means that they will see more usage per user since there will be so many more opportunities to use them. It may even be time to start measuring average usage per user (AUPU) as a more quantitative version of Larry Page's 'toothbrush test.'

Finally these apps are special because they're on devices that will eventually end up in the hands of every post-pubescent person on the planet. That means they will eventually end up with more users than anything we've seen so far.

In short...ubiquity.


Saturday, 21 December 2013

What is the state of the art in Android sharing?


I meet a lot of people in my job. Consequently I get to see lots of different companies trying to create the best possible Android sharing experience. Just about all of them start off with the standard sharing system based on intents and the standard chooser dialog.

It's compatible with just about all devices but it gives users an alphabetical list of applications even though many of these may not make sense in the given context. For example the list below shows the stock Email app even though I'm a Gmail user who has never configured the other email app on my tablet. This dialog also has issues for users who install lots of apps and its alphabetical ordering means we're starting to see developers gaming the system in order to be at the top of the list.
There's also the problem that the intents system doesn't let you customise the recipient other than by passing in a set of key-value pairs so developers (like The Guardian and Soundwave) offer an explicit Google+ share button in the action bar for users who are signed-in with Google+. This gives their users direct access to interactive posts. They also offer the standard chooser dialog as well.

The Gallery and Keep apps try to remember the last N apps the user has shared and present them to the user by using the ShareActionProvider added in Ice Cream Sandwich. Shazam's implementation is built on the same idea but does something slightly more sophisticated with it. It shows a list of the apps I've recently shared content to but adds various social services to the top of the list. It also knows which social service I signed-in with and adds it to the action bar as a separate button. The assumption is that I'm more likely to want to share newly discovered music to that social network than with the random assortment of apps on my device.


Snapette and Fancy implement simpler variants on the same idea. They hardcode a small set of social services (including Google+, Twitter and Facebook) even if they're not installed on the user's device. Clicking on those options takes users to a sign-in dialog before they can share. In their defence Fancy does offer a 'More' button that goes to the standard chooser dialog. This offers an escape hatch for users who want to share to contexts other than social networks.


Another alternative can be seen in the Spotify app. They make their own version of the standard chooser dialog but add a Spotify button to the top. That's because the standard chooser dialog doesn't give you much control over the order or the membership of the list it uses.

Unfortunately if you make your own chooser dialog you're going to have to expend a lot of effort to make it resemble the real thing. Or you can just show a simple list.


So what do I recommend? Ideally you should use the ShareActionProvider but nowadays a lot of apps are finding that deep integration with social services drives significant traffic and engagement. In that case...

If the screen is large enough then you should have your preferred share option in the action bar next to a button that launches a custom share list that shows your preferred apps with a More button that sends the user to the standard share dialog. This pushes users towards the developer's preferred networks (these could be the app's network or the services that the user has used to sign-in) but still gives users a way to get to all of apps they've installed.

On smaller screens you should have a share button that sends the user to a custom list containing the developer's preferred networks with a More button that sends users to the standard chooser dialog.

This approach balances simplicity of implementation, predictability (users shouldn't have to wonder why options are appearing and disappearing from their chooser dialog), extensibility, value to the developer and responsiveness to device size. This may seem complicated but fortunately a large amount of this can be implemented using the ShareActionProvider and its support for fine-grained tracking of history.

This is a complex and subtle topic with many different approaches being explored by lots of very smart people. I'm not going to pretend that this blog post is the final answer. After all, there's always the option of building something completely specific to your needs.

Wednesday, 11 December 2013

Migrating to Google+ Sign-in in 5 minutes

Are you looking to understand the available strategies for migrating your existing Google login solution to Google+ Sign-in? Well… You’ve certainly come to the right place
Who are you. You are you
If you're using OpenID1, OpenID2, OAuth1 or OAuth2Login then we have a detailed migration guide: https://developers.google.com/+/api/auth-migration

I strongly recommend reading it. Or at least skimming it since the social login market is bigger and more complicated than it seems. The following is merely a high-level restatement of the migration guide for people who aren't really sure which of the aforementioned technologies they're using.

If your existing system captures the user's email address using a Google identity solution then you can just:
  • migrate to Google+ sign-in
  • ask for the email OAuth scope
  • fetch the user's email address using one of our recommended approaches
  • look up the user in your database by email
  • associate them with the existing record that matches that email address since Google guarantees that the email addresses are valid
If your existing system doesn't capture the user's email address then life gets interesting.

If you're sure you're using OAuth1+OpenID2 then you can follow the instructions here: https://developers.google.com/+/api/auth-migration#oid2 which tell you how to fetch your old identifier and find out the equivalent identifier with Google+ Sign. Once that's done you can just associate the new identifier with the existing record and the user can sign-in in future with Google+ Sign-in.

If you're using something else then you can ask the user to sign-in twice: firstly with your existing Google identity solution then with Google+ Sign-in. Now that you have both identities you can associate them in your database. Once a critical mass of your users have gone through this process then you can stop using the legacy identity solution. If you have to use this option then I would also recommend reading Michael Mahemoff's experience report from Player.fm's migration: http://softwareas.com/migrating-user-accounts-from-google-openid-to-google-oauth-to-google-plus since I got the idea from him.

Wednesday, 13 November 2013

SCNA 2013 in memes

What was SCNA 2013 about? Well...the following memes kept coming up.
  • 10 thousand hours
  • Dreyfus model
  • Reasoning by analogy (chess, film making, agriculture)
  • TDD
  • Clojure
  • Code katas
  • Autonomy, purpose and mastery
  • Agile
  • Craftsmanship
  • Design Patterns
  • Javascript
  • Apple Macs
  • Apprenticeship
  • Rails
  • Professionalism
  • Quality
  • Community
  • Family
I also did a little lightning talk in which I tried to get people to change their minds about the Singleton pattern.
 Ceci n'est pas une Singleton

Monday, 7 October 2013

The screens in our future

Through historical accident, television has come to be seen as the first screen with our mobile devices as the second screen. This implies a mental model that's usually driven by television people who really mean that television is the primary screen whilst all others are merely secondary screens. When these devices are viewed from the perspective of the programme makers that is correct. But things change if we look at them from the perspective of the user.

When we look at usage it becomes clear that mobile devices (currently just phones and tablets) are the primary screen whilst television and desktop computers are the secondary screens.
Mobile is my screen.
Tablet is our screen.
TV is their screen.
-- Simon Davies and Ade Oshineye
The above quote is a synthesis of points made by Simon Davies and Ade Oshineye during an Internet Week panel discussion. They reflect a way of looking at screens/devices that may have surprising amounts of explanatory power.

The mobile (phone) screen is the most personal screen. It tends to belong to one person who carries it everywhere and seldom shares it. That person will customise it with a combination of apps and bookmarks that's practically a fingerprint. 

The tablet is large enough to be viewed by multiple people and is often shared within a family. As such it accumulates layers of choices from all the people who have used it. However it still tends to feel like a device that belongs to a small set of people. Whilst both of these devices empower people by giving them control over usage and content, the television is different. 

Whilst it may belong to one or many you're never allowed to forget that the content on your television is decided by other people. They decide what you can watch and when you can watch it. As for customisation…forget it.

The final step is to realise that we shouldn't be thinking about a fixed number of screens. We're facing a multi-screen future. That means there are going to be N categories of M screens in your life. And the values of N and M will only increase over time.

This is not a problem we will solve by building responsive websites with a fixed number of breakpoints. This is not a even problem we will solve by pouring the same content into a fixed number of buckets or screen sizes.

This is a Cambrian Explosion of contexts, interactions between contexts and user journeys across contexts. Time to adapt.

Plenty of room for more screens